Large language models are expensive to serve. A model like Llama 3.1 8B in BF16 precision occupies roughly 15GB of GPU memory. In BF16, each of the 8 billion parameters takes 2 bytes to store, which adds up to roughly 15GB just for the weights — and that’s not all. The GPU also needs memory for the KV cache (which stores context for every active request) and for the intermediate computations (“activations”) during inference. A single GPU with 16GB VRAM might technically fit the model weights, but with barely 1GB left for KV cache and activations, it would struggle to serve even a single request. These memory demands also directly limit how many requests you can serve concurrently and how fast each response is generated.
This creates a gap between what a model can do and where it can practically run. A model that performs well in a notebook may be too large, too slow, or too expensive to deploy in production, where latency, throughput, and hardware cost all matter.
One way to close that gap is quantization — reducing the precision of a model’s weights (and optionally its activations) to a lower-precision representation, whether integer (INT8, INT4) or floating point (FP8). A smaller representation means less memory, faster computation, and potentially more concurrent users — but it has to be done without degrading what the model is actually good at.
In this post, I take a Llama 3.1 8B Instruct model, compress it using INT8 W8A8 quantization with SmoothQuant and GPTQ, and measure exactly what changes in accuracy and system-level performance. I evaluate accuracy across four benchmarks covering knowledge, reasoning, commonsense, and instruction following; benchmark performance under load using vLLM and GuideLLM; and compare everything side by side.
The result: a model that is 46% smaller, generates tokens 44% faster at max load, handles 29% more concurrent requests — with no measurable accuracy loss on any of the four benchmarks.
This post walks through the full workflow, from compression to evaluation, and explains the concepts behind each step so you understand not just what was done, but why it works.
The Experiment: What We Built and Why
Before compressing a model — with quantization or any other technique — you need to know what you’re starting with. Without a baseline, there’s no way to measure what compression changed. Did accuracy drop? Did latency improve? By how much? You can’t answer these unless you measured the original model first, under the same conditions.
That’s why the workflow starts with benchmarking the base model before touching it. The full pipeline has six steps:
- Benchmark the base model’s accuracy using
lm-eval-harnessacross four tasks: MMLU, ARC, HellaSwag, and IFEval. - Benchmark the base model’s performance by serving it with vLLM and generating load with GuideLLM to measure latency, throughput, and concurrency.
- Compress the model using
llm-compressorwith INT8 W8A8 quantization (SmoothQuant + GPTQ). - Benchmark the compressed model’s accuracy, using the same benchmarks and conditions as step 1.
- Benchmark the compressed model’s performance, using the same serving setup and load conditions as step 2.
- Compare the accuracy and performance of both models side by side.
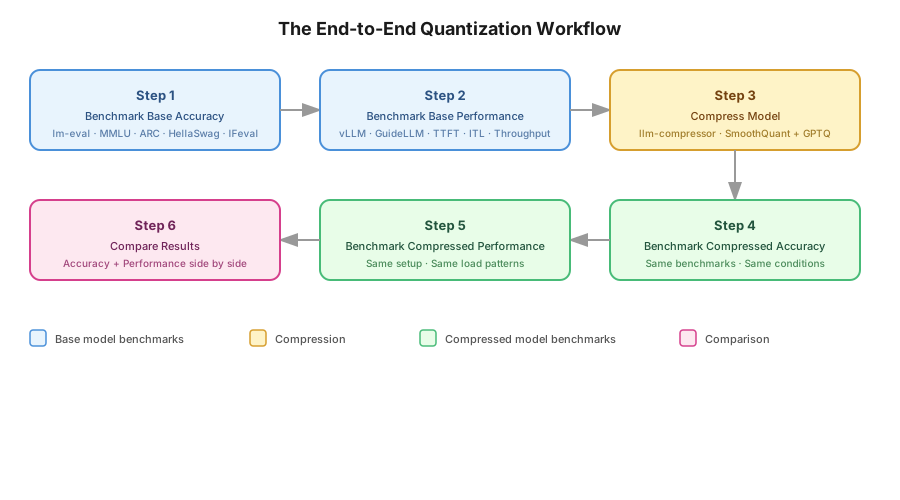
The consistency matters: both models are evaluated on the same benchmarks, served on the same hardware, and tested under the same load conditions, so any differences are attributable to compression — not to differences in the evaluation setup.
Hardware: single NVIDIA L40S GPU, 46GB VRAM.
Model: RedHatAI/Llama-3.1-8B-Instruct.
How the Model Was Compressed
llm-compressor was used to apply INT8 quantization to the base model’s weights and activations — a scheme called W8A8: both weights and activations are represented in 8-bit integers during matrix multiplication, which lets the GPU use its INT8 tensor cores. These are significantly faster than the BF16 tensor cores the uncompressed model relies on.
At its core, quantizing a weight involves two steps — scaling and rounding:
scale = max(abs(weight_column)) / 127
quantized_weight = round(weight / scale)
You find the maximum value in a weight column, divide by 127 (the largest positive INT8 value) to get a scale, then divide every weight in that column by that scale and round to the nearest integer. The rounding is where information is lost. Each weight picks up a small error, and across billions of weights these errors accumulate and can shift a layer’s output away from what it should be. Since each layer’s output becomes the next layer’s input, that error compounds through every subsequent layer.
A second challenge is activation quantization. During inference, activations are also quantized to INT8 before each matrix multiplication, using a single scale computed dynamically, at runtime, across all channels of a given token’s activation. The problem: activations can have persistent outlier values in certain channels, and a single shared scale can’t handle both the outlier and the small values without destroying one or the other.
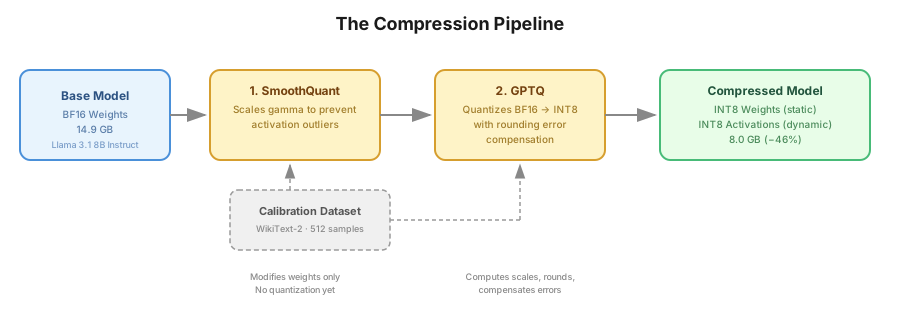
To handle both problems, the pipeline runs two algorithms in sequence:
- SmoothQuant handles the activation-outlier problem by modifying the weights before quantization, so the activations they produce are smoother.
- GPTQ then calibrates the weight values before they’re rounded to INT8, using error compensation to minimize the rounding damage.
The compression pipeline
Why Naive Weight Quantization Doesn’t Work, and How GPTQ Fixes It
Because weight quantization happens offline (in advance, not at runtime), it’s affordable to compute a separate quantization scale for each channel (column) of the weight matrix, rather than one scale for the whole tensor.
Naive quantization (round-to-nearest) divides a column by its scale and rounds to the nearest integer. Here’s a small worked example — a weight matrix with two columns (channels):
Weight matrix:
        ch0    ch1
row0:  0.31   0.82
row1:  0.74   0.45
row2:  0.52   0.93
Compute a quantization scale per channel:
scale_ch0 = max(ch0) / 127 = 0.74 / 127 = 0.005827
scale_ch1 = max(ch1) / 127 = 0.93 / 127 = 0.007323
Quantize each column (round(weight / scale)):
Quantized weight matrix (INT8):
        ch0    ch1
row0:    53    112
row1:   127     62
row2:    89    127
To see how much error rounding introduced, reverse the scaling (multiply back by the scale) and compare to the original:
Reconstructed:            Original:
        ch0     ch1               ch0    ch1
row0:  0.3088  0.8202     row0:  0.31   0.82
row1:  0.7400  0.4540     row1:  0.74   0.45
row2:  0.5186  0.9300     row2:  0.52   0.93
There’s a small gap — that’s the rounding error. Now push a sample input activation [1.0, 2.0, 0.5] through both weight matrices:
Original output:      ch0 = 1.0·0.31 + 2.0·0.74 + 0.5·0.52 = 2.050
                       ch1 = 1.0·0.82 + 2.0·0.45 + 0.5·0.93 = 2.185

Reconstructed output:  ch0 = 1.0·0.3088 + 2.0·0.7400 + 0.5·0.5186 = 2.048
                       ch1 = 1.0·0.8202 + 2.0·0.4540 + 0.5·0.9300 = 2.193
| Channel | Original | Reconstructed | Error |
|---|---|---|---|
| ch0 | 2.050 | 2.048 | −0.002 |
| ch1 | 2.185 | 2.193 | +0.008 |
The errors are tiny here because each channel only has 3 weights. In Llama 3.1 8B, each channel has 4,096 weights across 32 layers — these small per-weight rounding errors accumulate across thousands of weights, and the resulting output error flows into the next layer as a slightly-wrong activation, which gets multiplied by the next layer’s weights, potentially amplifying the error through every subsequent layer.
How GPTQ improves on naive quantization
Naive quantization rounds every weight and moves on, letting rounding errors accumulate uncorrected. GPTQ adds a compensation step: after rounding each weight, it measures the error that was just introduced and adjusts the remaining unquantized weights to correct for it.
Revisiting the example: the first weight in channel 0 was 0.31, which after quantization and reconstruction became 0.3088 — a rounding error of −0.0012. Naive quantization ignores this. GPTQ instead distributes that error across the remaining unquantized weights in the channel, nudging them slightly before they’re quantized, so the channel’s total output stays close to the original (2.050). This repeats: quantize one weight, measure the error, redistribute it to what’s left, and continue until every weight in the channel is quantized.
Not every weight can safely absorb redistributed error, though — some barely affect the output and can take on more error safely, while others have a strong influence and would be damaged further. GPTQ uses the Hessian — a matrix computed from the calibration dataset — to measure this sensitivity and decide where the error goes.
The Hessian comes from feeding a small calibration dataset (input samples only, no labels) through the model and observing how much the layer’s output would change if each weight were perturbed slightly. High-Hessian weights strongly affect the output, so GPTQ avoids pushing error onto them; low-Hessian weights barely matter and can absorb more.
The full GPTQ process, per layer:
- Feed calibration data through the layer; record the original output.
- Compute the Hessian from the calibration activations.
- Quantize the first weight; measure the rounding error.
- Use the Hessian to redistribute that error across the remaining unquantized weights (more to unimportant weights, less to important ones).
- Quantize the next weight, measure error, redistribute again.
- Repeat until every weight in the layer is quantized.
- The final output approximates the original.
One practical detail, independent of which algorithm is used: the lm_head layer — which projects the model’s hidden representation (4,096 dimensions in Llama 3.1 8B) into vocabulary logits (~128k tokens) — is typically excluded from quantization and kept in full precision. Token selection depends directly on these logits, so rounding error here can change which token gets picked, potentially altering the entire response.
Why Activation Quantization Is Hard, and How SmoothQuant Fixes It
Activations produced by a given layer can persistently have outlier values in specific channels, and that makes activation quantization difficult.
Activations are quantized per token, dynamically, at runtime — a single scale is computed across all channels of that token’s activation (the activation tensor is 1D). Per-channel scaling isn’t an option here: activation channels sit on the inner axis of the dot product, so they get summed together during matrix multiplication, and once combined into a single sum, individual per-channel scales can’t be reversed afterward. A single shared scale avoids that problem, but creates a new one: if even one channel has an outlier, that outlier dominates the scale and destroys all the smaller values.
Worked example — an activation tensor with one outlier channel:
activations = [1.32, 0.75, 0.91, 153.0]
scale = max(|activations|) / 127 = 153.0 / 127 = 1.205

1.32 / 1.205 = 1.10  → rounds to 1   (squashed)
0.75 / 1.205 = 0.62  → rounds to 1   (squashed)
0.91 / 1.205 = 0.76  → rounds to 1   (squashed)
153.0 / 1.205 = 127.0 → rounds to 127 (perfect)

quantized = [1, 1, 1, 127]
The outlier is preserved perfectly; everything else is destroyed. SmoothQuant addresses this before quantization happens.
Where the outlier actually comes from
The output of one layer’s matrix multiplication doesn’t go straight into the next layer’s weights — it first passes through a normalization layer (RMSNorm, for Llama 3.1 8B). RMSNorm does two things: it divides every value by the vector’s root-mean-square (stabilizing overall magnitude), then multiplies the result, channel by channel, by a trained vector called gamma — one fixed value per channel, learned during training, applied identically to every token at inference. This second step is where a persistent outlier comes from: since gamma is fixed and identical for every token, a large gamma value in one channel stretches that channel by the same amount every time.
Worked example — after RMS normalization:
normalized = [1.32, 0.75, 0.91, 1.53]     (relatively balanced)
gamma      = [1, 1, 1, 100]               (channel 3 has a large learned value)

activation = normalized × gamma (elementwise)
           = [1.32, 0.75, 0.91, 153.0]
That’s the same outlier-producing activation from before — and now it’s clear the outlier came from gamma, not from any weight matrix.
SmoothQuant’s fix: scale gamma down on the outlier channel, and compensate by scaling the next layer’s weights up by the same factor on the matching input channel — so the model’s overall behavior is unchanged, just redistributed between the normalization layer and the next linear layer. Scaling weights up is safe because GPTQ already quantizes weights with per-channel scales, so a large value in one column doesn’t affect any other column.
Same example, with gamma smoothed by a factor of 100 on channel 3:
normalized (unchanged) = [1.32, 0.75, 0.91, 1.53]
gamma (smoothed)        = [1, 1, 1, 1]

activation = [1.32, 0.75, 0.91, 1.53]     (no more outlier)

scale = 1.53 / 127 = 0.012
110 = round(1.32 / 0.012)   ← well represented
63  = round(0.75 / 0.012)   ← well represented
76  = round(0.91 / 0.012)   ← well represented
127 = round(1.53 / 0.012)   ← perfect

quantized = [110, 63, 76, 127]
| Channel | Without SmoothQuant | With SmoothQuant |
|---|---|---|
| ch0 | 1 | 110 |
| ch1 | 1 | 63 |
| ch2 | 1 | 76 |
| ch3 | 127 | 127 |
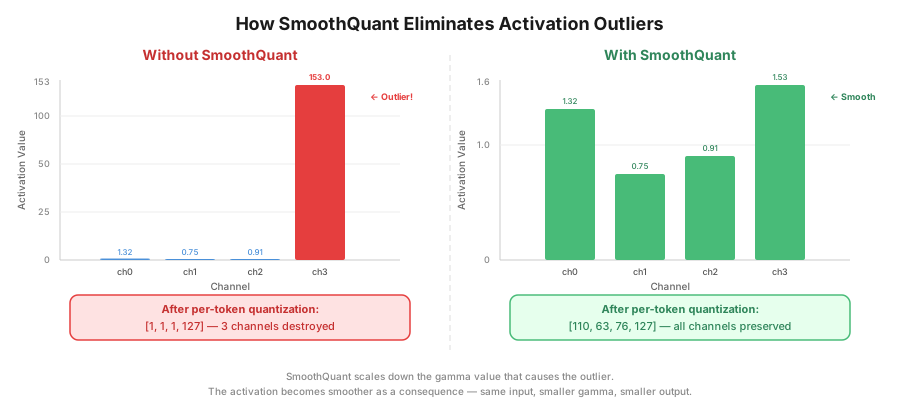
Without SmoothQuant, three of four channels are destroyed. With it, all four are well represented — the outlier was eliminated before quantization, not by touching activations directly, but by scaling down the gamma value that caused it.
How the smoothing factor is computed
SmoothQuant needs to observe real activations to know which channels have outliers and how large they are — so, like GPTQ, it uses a calibration dataset (input samples, no labels) fed through the model. For each channel j, it computes a smoothing factor:
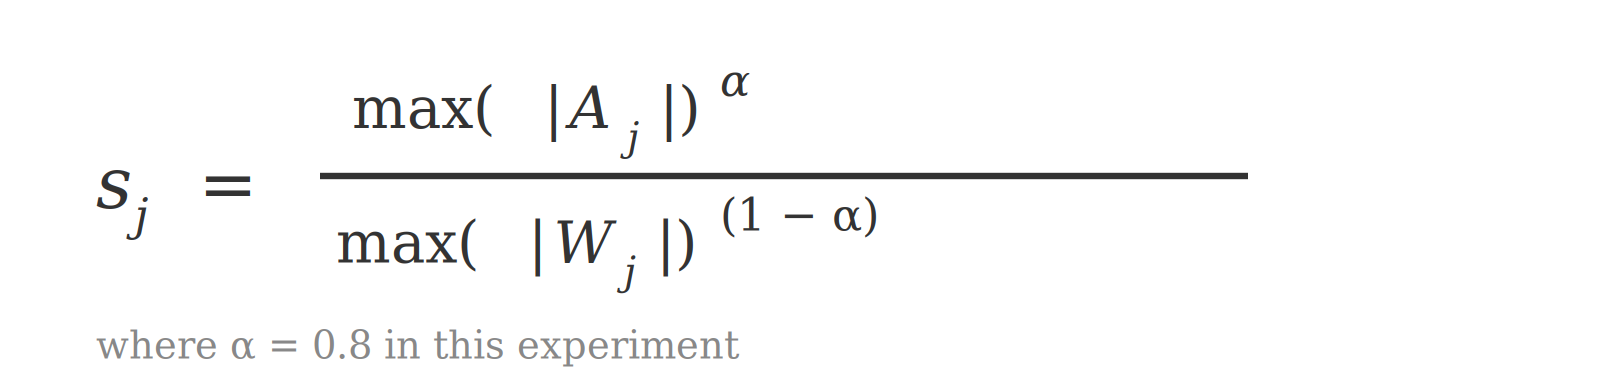
where A_j is the largest activation value observed in channel j across calibration samples, W_j is the largest weight value in the corresponding row of the receiving linear layer, and α (alpha) controls how aggressively “difficulty” is shifted from activations to weights (α = 0.8 in this experiment, meaning most of it shifts to the weights).
This formula naturally produces a large s for channels with outliers (gamma gets scaled down a lot there) and a small s (close to 1) for normal channels (gamma barely changes) — the smoothing is proportional to how bad the outlier is.
After computing s per channel, SmoothQuant divides RMSNorm’s gamma by s and multiplies the matching row of the next layer’s weights by the same s. The weights are still BF16 at this point — smoothed, but not yet quantized. GPTQ takes over from there.
Why the Calibration Dataset Matters
Both SmoothQuant and GPTQ depend on the same calibration dataset, but use it for different things: SmoothQuant uses the recorded activations to find which channels have outliers and how severe they are; GPTQ uses them to compute the Hessian, which measures how sensitive each weight is. Both measurements are only as good as how well the calibration data represents real production inputs — mismatched calibration data means SmoothQuant might smooth the wrong channels while GPTQ protects the wrong weights, producing more accuracy loss than necessary.
This experiment used WikiText-2, a general-purpose encyclopedia-style text dataset, to calibrate an instruction-tuned chat model. In terms of domain, WikiText-2 aligns reasonably with three of the four evaluation benchmarks (MMLU, ARC, and HellaSwag all test general knowledge, similar to Wikipedia’s coverage); IFEval is domain-agnostic. In terms of style, WikiText-2 is descriptive prose, while the benchmarks use questions, scenario completions, and direct commands — a mismatch, since the model itself was tuned for questions and commands, not passive prose.
Despite that mismatch, accuracy held up across all four benchmarks — suggesting the quantization process is fairly robust even with imperfect calibration data, and that these results can be read as a conservative lower bound. In production, a calibration set matched to the deployment’s actual domain and style (e.g. UltraChat for a chat application) would likely do at least as well.
The Result: Model Size
After SmoothQuant + GPTQ with WikiText-2 as calibration, the model dropped from 14.9GB to 8.0GB — a 46% reduction.
BF16: 8,000,000,000 weights × 2 bytes = 16,000,000,000 bytes ≈ 14.9 GB
INT8: 8,000,000,000 weights × 1 byte  =  8,000,000,000 bytes ≈  7.5 GB
The actual compressed model lands at 8.0GB rather than the theoretical 7.5GB because some components (like lm_head) stay in BF16, and quantization scales are stored alongside the INT8 weights.
Accuracy After Quantization: Did We Lose Anything?
Both models were evaluated with lm-eval-harness under identical conditions — zero-shot, same tasks, same hardware — across four benchmarks: MMLU (factual knowledge, 57 subjects), ARC Easy (scientific reasoning), HellaSwag (commonsense reasoning), and IFEval (instruction following).
| Benchmark | Base Accuracy | Compressed Accuracy | Delta |
|---|---|---|---|
| MMLU | 0.6322 | 0.6311 | −0.0011 |
| ARC Easy (acc) | 0.8136 | 0.8106 | −0.0030 |
| HellaSwag (acc_norm) | 0.7251 | 0.7277 | +0.0026 |
| IFEval (inst strict) | 0.8189 | 0.8237 | +0.0048 |
Some benchmarks moved slightly down, some slightly up — but are these differences meaningful, or just noise?
Interpreting the deltas: standard error
lm-eval reports a standard error per benchmark, which quantifies how much a score would naturally vary if you re-ran the same evaluation on the same model. If the delta between base and compressed is smaller than that natural variation, it isn’t a real, attributable effect of quantization — it’s noise.
| Benchmark | Delta | Standard Error | Delta within noise? |
|---|---|---|---|
| MMLU | −0.0011 | ±0.0038 | Yes (3.5× smaller) |
| ARC Easy | −0.0030 | ±0.0080 | Yes (2.7× smaller) |
| HellaSwag | +0.0026 | ±0.0045 | Yes (1.7× smaller) |
| IFEval | +0.0048 | not reported | Likely (similar magnitude) |
Every observed delta is smaller than its standard error — meaning the differences between base and compressed are indistinguishable from the benchmarks’ own natural run-to-run variation. Quantization did not measurably degrade accuracy on any of the four benchmarks.
Breaking MMLU down by its four subject categories tells the same story — all deltas stay within noise:
| MMLU Category | Base | Compressed | Delta |
|---|---|---|---|
| Humanities | 0.5864 | 0.5911 | +0.0047 |
| STEM | 0.5062 | 0.5043 | −0.0019 |
| Social Sciences | 0.7442 | 0.7394 | −0.0048 |
| Other | 0.7184 | 0.7132 | −0.0052 |
How this compares to other quantization schemes
Red Hat AI has published a W8A16 quantized version of the same model (also GPTQ, via llm-compressor), reporting accuracy within 1% of the unquantized baseline. These W8A8 results are consistent with that — accuracy is well preserved at 8-bit precision. (Note the comparison is directional rather than exact: this experiment used zero-shot raw-text prompting with log-likelihood scoring, while Red Hat AI’s used 5-shot chat-template prompting with generation-based scoring.)
The real difference between W8A8 and W8A16 isn’t accuracy — it’s inference speed. W8A8 quantizes both weights and activations to INT8, enabling faster computation via INT8 tensor cores. W8A16 only quantizes weights (activations stay BF16), so it shrinks the model but doesn’t speed up compute.
Performance After Quantization: What Did We Gain?
Accuracy tells you whether the model’s capabilities survived compression. Performance tells you whether compression delivered on its promise — a smaller, faster model that handles more traffic. Both models were served on identical hardware (single L40S GPU) with vLLM, using GuideLLM to generate concurrent, production-like traffic (1024 input tokens / 512 output tokens per request) at increasing rates.
| Metric | Base | Compressed | Change |
|---|---|---|---|
| Model size | 14.9 GB | 8.0 GB | −46% |
| Max concurrency | 34 requests | 44 requests | +29% |
| TTFT (sync) | 115.9 ms | 87.9 ms | −24% |
| TTFT (max load) | 147.0 ms | 119.7 ms | −19% |
| ITL (sync) | 22.2 ms | 14.7 ms | −34% |
| ITL (max load) | 39.6 ms | 34.5 ms | −13% |
| Throughput (max load) | 576.5 tok/s | 829.7 tok/s | +44% |
| Request latency (sync) | 11.4 s | 7.6 s | −33% |
| Request latency (max load) | 20.4 s | 17.8 s | −13% |
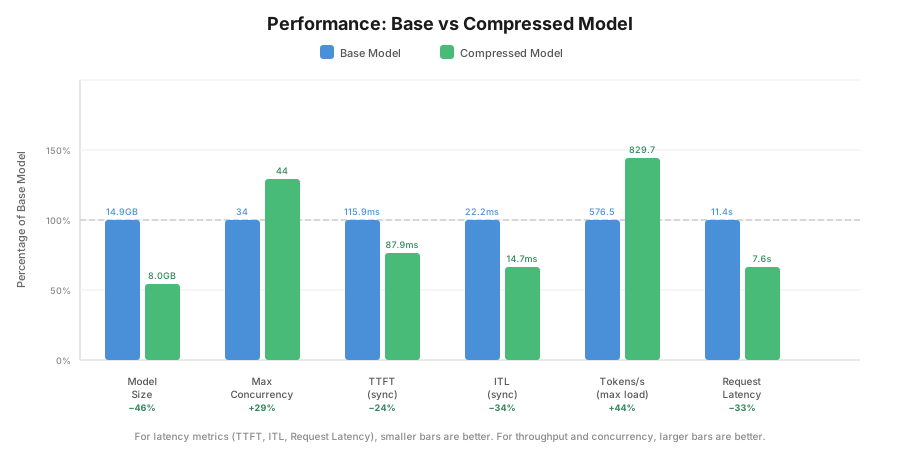
Concurrency: +29%
More concurrent requests fit because the compressed model occupies ~7GB less GPU memory, and that freed memory goes straight to the KV cache — the per-request store of intermediate Key/Value tensors computed at every layer, needed so the model doesn’t recompute earlier tokens at every generation step. Since each concurrent request needs its own KV cache, more free memory means more requests can be active at once.
Time to First Token (TTFT): −19% to −24%
TTFT is dominated by the prefill phase — processing the entire input prompt through all 32 layers before generating anything. Because both weights and activations are INT8 in W8A8, the matrix multiplications run on the GPU’s INT8 tensor cores, which are faster than BF16 tensor cores — faster prefill, faster first token. This is the compute speedup W8A16 can’t provide, since its activations stay in BF16 and its matmuls still run on BF16 tensor cores.
Inter-Token Latency (ITL): −13% to −34%
ITL — the time between each subsequent generated token — benefits from the same INT8 speedup. Notice the improvement is much larger at low concurrency (−34%) than at max load (−13%): that’s the cost of dynamic activation quantization. Each layer, for each token, has to measure the activation’s range, compute a scale, convert to INT8, run the matmul, and convert back to BF16 — steps that don’t exist in the base model and add overhead on every generated token.
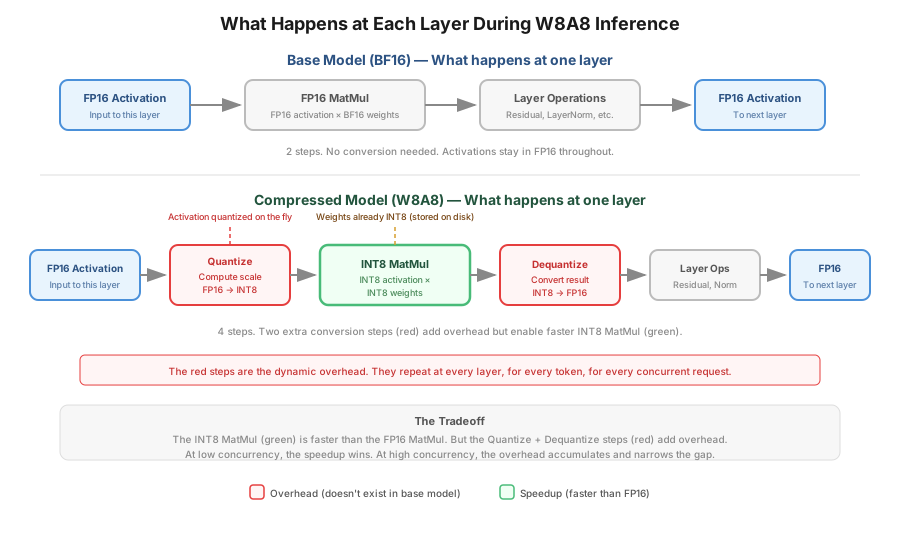
At 44 concurrent requests × 32 layers, that’s 1,408 quantize-dequantize cycles per decode step. The INT8 matmul itself becomes compute-bound (the weight matrix loads once and is reused across all concurrent requests), while the quantize/dequantize steps stay memory-bound (each activation must be individually loaded and converted, with no shared cost across requests). That’s why the quantize-dequantize overhead eats a growing share of total time as concurrency rises, shrinking the ITL improvement from 34% down to 13%.
Throughput: +44%
Tokens-per-second combines two effects: faster per-token generation (INT8 tensor cores) and higher concurrency (more KV cache room). Together: 576.5 → 829.7 tokens/sec at max load.
The ITL degradation ratio — a real but bounded tradeoff
The ITL degradation ratio (ITL at max concurrency ÷ ITL at sync) measures how much slower token generation gets as load increases:
Base:       39.6 / 22.2 = 1.78×
Compressed: 34.5 / 14.7 = 2.34×
The compressed model’s ITL degrades faster under load — the cost of dynamic activation quantization overhead compounding with concurrency. But context matters: even after degrading faster, the compressed model’s ITL at max load (34.5 ms) is still lower than the base model’s ITL at max load (39.6 ms). It starts from a much better baseline (14.7 ms vs. 22.2 ms), so it never actually becomes worse than the base model across the tested range.
SLO check
Defined SLO: TTFT ≤ 200ms for 95% of requests (p95) at max concurrency.
| Model | Max concurrency | p95 TTFT | Meets SLO? |
|---|---|---|---|
| Base | 34 | 162.4 ms | ✓ |
| Compressed | 44 | 136.0 ms | ✓ |
Both models meet the SLO — meaning the base model would already have been “good enough” for this specific use case. But since compression came at no accuracy cost, it’s a straightforward win: same SLO compliance, more headroom, and the ability to serve more users on the same hardware.
Takeaways and Recommendations
Compressing Llama 3.1 8B Instruct from 14.9GB to 8.0GB with W8A8 INT8 (SmoothQuant + GPTQ) did not measurably degrade accuracy across four benchmarks spanning factual knowledge, scientific reasoning, commonsense reasoning, and instruction following — every observed delta was smaller than the benchmarks’ own standard error. On the performance side, the compressed model handled 29% more concurrent requests, generated tokens 44% faster at max load, and cut time-to-first-token by up to 24%. The one real tradeoff was a higher ITL degradation ratio under high concurrency (the cost of dynamic activation quantization) — but even so, its absolute latency stayed lower than the base model’s across the full tested load range.
When W8A8 INT8 is a good fit:
- Single-GPU deployments where memory is the constraint
- Server-side inference where throughput and concurrency matter
- Latency-sensitive applications that need faster time-to-first-token
- Cases where you want both memory savings and compute speedup (unlike W8A16, which only saves memory)
- Deployments on a wide range of hardware — INT8 is supported on older architectures like Ampere GPUs, and even CPUs (FP8 has become popular too, since it skips calibration algorithms like SmoothQuant/GPTQ entirely — but it needs newer hardware such as Ada Lovelace, Hopper, or Blackwell)
What to watch out for:
- ITL degrades faster under high concurrency due to dynamic activation quantization overhead — monitor ITL scaling behavior for very high-concurrency workloads.
- Calibration data quality matters. WikiText-2 was used here for simplicity, but a calibration set matched to your deployment’s domain and style will likely do equal or better.
- Keep
lm_headin full precision to avoid degrading token-selection quality.
What to explore next:
- A domain-matched calibration dataset (e.g. UltraChat for chat applications), to see if accuracy holds up even further
- W4A16 quantization for cases where memory savings matter more than compute speedup
- FP8 quantization, gaining support on newer GPU architectures
- Multi-GPU serving, to distribute dynamic quantization overhead and reduce ITL degradation at high concurrency
The full end-to-end example — notebooks and documentation for every step from benchmarking to compression to deployment — is available at model-serve-flow.
References
Algorithms
- SmoothQuant: Xiao et al., “SmoothQuant: Accurate and Efficient Post-Training Quantization for Large Language Models” (2022)
- GPTQ: Frantar et al., “GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers” (2022)
Evaluation benchmarks
- MMLU: Hendrycks et al., “Measuring Massive Multitask Language Understanding” (ICLR 2021)
- ARC: Clark et al., “Think you have Solved Question Answering? Try ARC, the AI2 Reasoning Challenge” (2018)
- HellaSwag: Zellers et al., “HellaSwag: Can a Machine Really Finish Your Sentence?” (ACL 2019)
- IFEval: Zhou et al., “Instruction-Following Evaluation for Large Language Models” (2023)
Tools
Models and datasets